Benchmarks show 48–55% higher training throughput compared with TorchTitan and up to 34% faster hosted training with prime-rl.
The optimization was tested on Qwen3-30B-A3B and Qwen3-235B-A22B using NVIDIA H200 GPUs.
Benchmark Results: Prime Mega MoE vs. TorchTitan
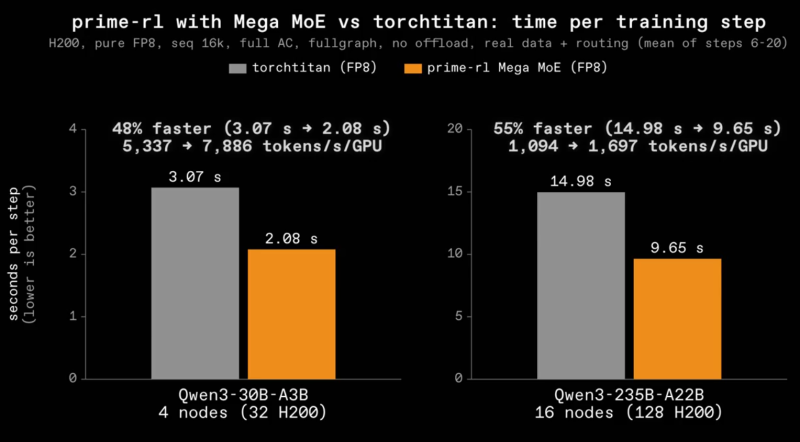
Image source: Prime Intellect. Training step times and throughput on NVIDIA H200 GPUs.
| Metric | Qwen3-30B-A3B | Qwen3-235B-A22B |
| GPUs | 32 × H200 | 128 × H200 |
| TorchTitan step time | 3.07 s | 14.98 s |
| Prime Mega MoE step time | 2.08 s | 9.65 s |
| Step-time reduction | 32.2% | 35.6% |
| TorchTitan throughput | 5,337 tokens/s/GPU | 1,094 tokens/s/GPU |
| Prime Mega MoE throughput | 7,886 tokens/s/GPU | 1,697 tokens/s/GPU |
| Throughput improvement | +48% | +55% |
The larger Qwen3-235B-A22B model recorded the biggest improvement, with throughput increasing from 1,094 to 1,697 tokens/s/GPU.
Technical Specifications
| Parameter | Specification |
| Kernel | DeepSeek Mega MoE, extended for training |
| Architecture | Mixture of Experts (MoE) |
| Tested models | Qwen3-30B-A3B, Qwen3-235B-A22B |
| Nominal total parameters | 30B / 235B |
| Nominal active parameters | 3B / 22B |
| Hardware | NVIDIA H200 |
| Precision | FP8 |
| Sequence length | 16,384 tokens |
| Activation checkpointing | Full |
| Compilation | Full graph |
| CPU offloading | Disabled |
| Measurement | Mean of steps 6–20 |
Benchmarks used real training data with expert routing.
Comparison With Previous Implementation
Prime Mega MoE adds backward propagation to DeepSeek's original Mega MoE kernel, which focused on forward computation.
| Feature | Original Mega MoE | Prime Mega MoE |
| Optimized forward pass | Yes | Yes |
| Backward propagation | Not provided | Supported |
| Gradient-based training | Requires separate implementation | Supported |
| Fused expert computation | Yes | Yes |
| Integration with prime-rl | No | Yes |
The optimized implementation targets token dispatch, expert computation, output aggregation and gradient propagation, reducing communication and synchronization overhead.
Performance Summary
- +48% throughput: Qwen3-30B-A3B on 32 H200 GPUs.
- +55% throughput: Qwen3-235B-A22B on 128 H200 GPUs.
- Up to +34% throughput: Hosted training compared with the existing prime-rl implementation.
- 32–36% shorter training steps: Across both TorchTitan comparisons.
These are training performance results, not improvements in model accuracy or inference speed. Performance on other GPU configurations and models has not been established by these benchmarks.