The leading agent, GPT-6 Astra, fully completes 47% of tasks, while five evaluated agents achieve zero perfect completions.
Technical Specifications
| Parameter | Odysseys2 |
| Release date | October 27, 2026 |
| Benchmark tasks | 100 |
| Task source | Real user requests |
| Execution environment | Live web |
| Time limit | 60 minutes per task |
| Evaluation criteria | 8–12 per task |
| Total rubric checks | 982 |
| Graded attempts | 2,480 |
| Main agent configurations | 20 |
| Evaluation model | GPT-5.6 Luna (xhigh) |
Tasks involve multi-site research, data verification, document creation and structured information extraction.
Agent Performance
| AI Agent | Fully Completed Tasks |
| GPT-6 Astra | 47/100 |
| Claude Opus 5.5 (high) | 18/100 |
| GPT-5.6 Sol | 15/100 |
| Grok 4.7 (high) | 13/100 |
| GPT-5.6 Luna (high) | 8/100 |
| Gemini 3.8 Flash (high) | 0/100 |
GPT-6 Astra achieves an average rubric score of 84.6/100, despite completing only 47 tasks perfectly. This indicates that many attempts satisfy most requirements but fail at least one condition.
Odysseys vs. Odysseys2
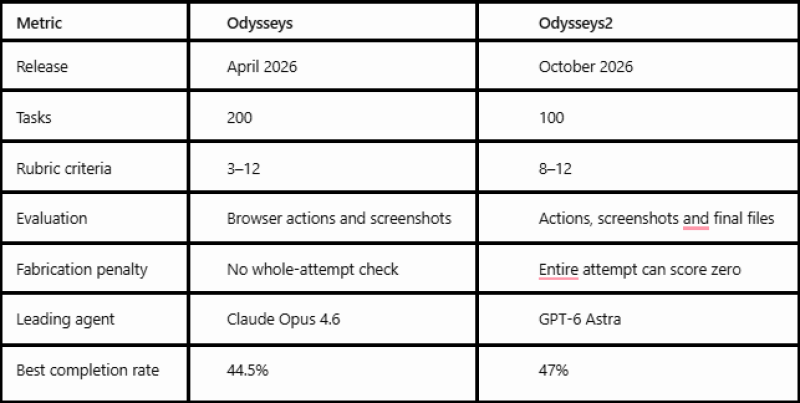
The two completion rates are not directly comparable because the datasets and evaluation methods differ.
Evaluation impact: When the same 100 GPT-6 Astra attempts are assessed using both methods:
- Original-style evaluator: 86/100 perfect completions.
- Odysseys2 evaluator: 47/100 perfect completions.
The stricter evaluation reduces the measured success rate by 39 percentage points.
Reliability and Execution Cost
| Metric | GPT-5.6 Luna (high) | Claude Opus 5.5 (high) |
| Median execution time | ~13 minutes | ~25 minutes |
| Model cost per task | $0.27 | $5.33 |
Five repeated runs of GPT-5.6 Luna produced mean rubric scores between 54.9 and 60.2, indicating measurable performance variability.
Key Findings
- GPT-6 Astra leads with 47% perfect task completion.
- Five evaluated agents fail to complete any task perfectly.
- Strict deliverable verification significantly reduces reported success rates.
- High rubric scores do not guarantee complete, correct outputs.
- Reliability, execution time and cost remain major limitations for autonomous web agents.
Conclusion:
Odysseys2 demonstrates that even leading web agents struggle with fully completing long-horizon workflows. GPT-6 Astra satisfies 84.6% of rubric criteria on average but achieves perfect completion on fewer than half of the tasks.