The model supports 40 languages, speaker diarization, translation, contextual prompting, and audio understanding. It ranked first among 14 systems in VoiceArena's Diarization-Bench v1.
Technical Specifications
| Specification | Nemotron 3.5 Transcribe |
| Architecture | Hybrid Mamba-2–Transformer MoE |
| Total parameters | ~34B, including audio encoder |
| Active parameters | ~4.3B |
| Languages | 40 |
| Context window | 65,536 tokens |
| Maximum audio duration | 1 hour |
| Precision | BF16, FP8, NVFP4 |
| Capabilities | ASR, diarization, translation, audio Q&A |
| Deployment | NVIDIA H100 80GB (BF16) |
| License | OpenMDW-1.1 |
The model also supports word-level timestamps and contextual vocabulary prompts for improving recognition of names and specialized terminology.
VoiceArena Benchmark Results
Nemotron 3.5 Transcribe achieved 32.4% cpWER (concatenated permutation word error rate) on VoiceArena's Diarization-Bench v1, which tests transcription accuracy and speaker attribution in full English recordings, including overlapping speech.
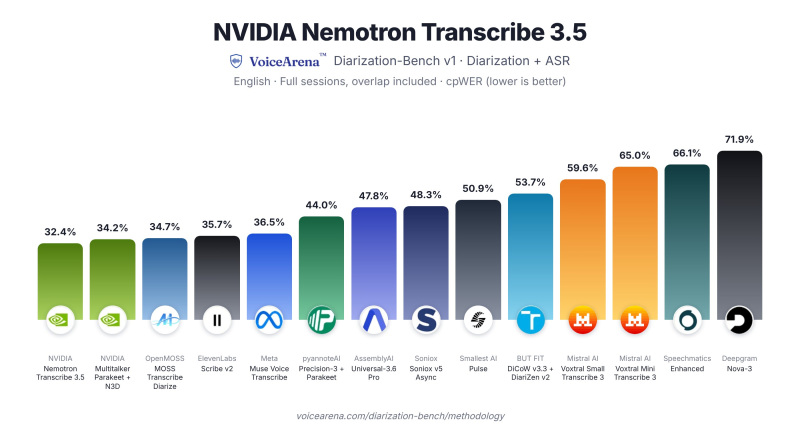
NVIDIA Nemotron Transcribe 3.5 — VoiceArena Diarization-Bench v1 (the supplied 14-model comparison chart).
| Model | cpWER |
| NVIDIA Nemotron Transcribe 3.5 | 32.4% |
| NVIDIA Multitalker Parakeet + N3D | 34.2% |
| OpenMOSS MOSS Transcribe Diarize | 34.7% |
| ElevenLabs Scribe v2 | 35.7% |
| Meta Muse Voice Transcribe | 36.5% |
| AssemblyAI Universal-3.6 Pro | 47.8% |
| Mistral AI Voxtral Small Transcribe 3 | 59.6% |
| Deepgram Nova-3 | 71.9% |
Nemotron's cpWER is 1.8 percentage points lower than NVIDIA's Multitalker Parakeet + N3D, 3.3 points lower than ElevenLabs Scribe v2, and 4.1 points lower than Meta Muse Voice Transcribe.
Additional ASR Benchmarks
| Benchmark | Nemotron 3.5 | Competitor |
| English ASR WER | 4.71% | Qwen3-ASR: 4.94% |
| Multilingual ASR WER | 4.62% | Qwen3-ASR: 6.49% |
| Long-form ASR WER | 10.98% | Parakeet v3: 13.37% |
| Multi-speaker cpWER | 15.80% | DiCoW + DiariZen: 16.83% |
These results come from separate benchmarks and are not directly comparable with VoiceArena scores.
Comparison With Previous Nemotron ASR
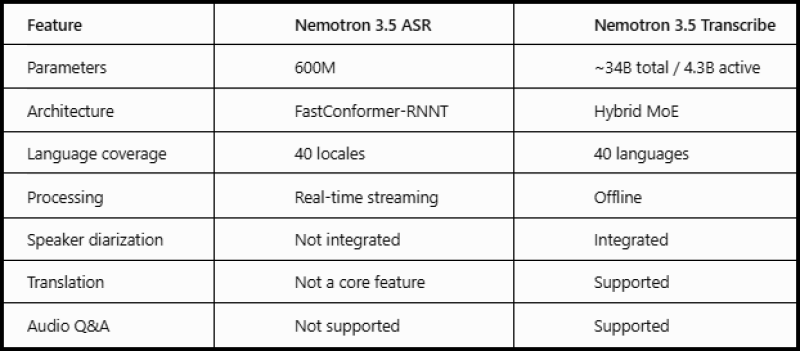
The previous 600M-parameter model targets low-latency streaming transcription. Nemotron 3.5 Transcribe adds integrated speaker identification, translation, and audio reasoning at substantially higher computational cost.
Inference Performance
NVIDIA reports the following results using its optimized serving stack:
| Metric | Result |
| Processing throughput | 2,238 audio seconds/second |
| 30-second recording | ~0.13-second processing time |
| GPU | RTX PRO 6000 Blackwell |
| Quantization | NVFP4 |
| Acceleration | DFlash2 speculative decoding |
These figures represent optimized benchmark conditions rather than guaranteed performance in standard local deployments.
Availability
Nemotron 3.5 Transcribe was released on October 28, 2026. Model weights are available in BF16, FP8, and NVFP4 under the OpenMDW-1.1 license.