According to the published benchmark charts, Kimi K3.1 Pro leads six of 14 evaluations, outperforming Claude Opus 5.5 and GPT-6 Astra in several coding, reasoning and agentic tasks. Open weights are scheduled for November 4, 2026.
Kimi K3.1 Pro Specifications
| Specification | Kimi K3.1 Pro |
| Developer | Moonshot AI |
| Architecture | Mixture-of-Experts (MoE) |
| Total parameters | 2.8 trillion |
| Active parameters | 104 billion |
| Active parameter ratio | 3.71% |
| Context window | Not disclosed |
| Open weights | November 4, 2026 |
| License | Not disclosed |
The MoE architecture activates approximately 3.71% of total parameters during inference, reducing active computation compared with a dense model of equivalent total size.
Kimi K3.1 Pro vs Claude Opus 5.5 and GPT-6 Astra
The supplied benchmark results cover coding, agentic tasks, scientific reasoning, tool use and professional workflows.
Kimi K3.1 Pro takes first place across all models shown in six benchmarks, including SWE Marathon, Agents' Last Exam, OfficeQA Pro v2, Humanity's Last Exam, GDP.pdf and ZeroBench.
The model is particularly competitive in software engineering:
- SWE Marathon: 51.7, compared with 46.3 for Opus 5.5.
- Terminal-Bench 4.0: 65.7%, only 0.7 percentage points behind Opus 5.5.
- Humanity's Last Exam with tools: 70.0, versus 67.7 for Opus 5.5 and 57.2 for GPT-6 Astra.
Its weakest relative result is Terminal-Bench Science 01, where Kimi scores 38.1 against GPT-6 Astra's 68.1.
Performance vs Inference Cost
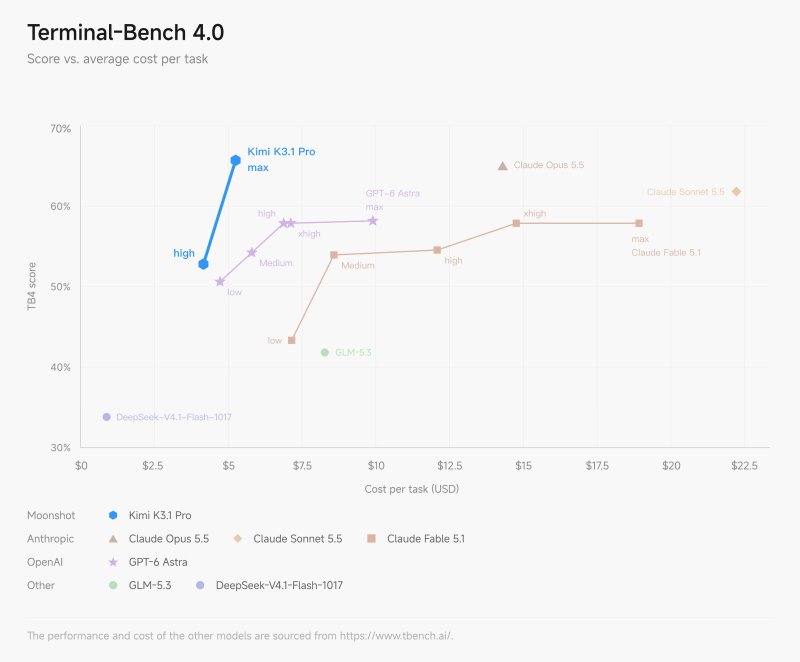
The accompanying Terminal-Bench 4.0 chart compares benchmark scores with average cost per completed task.
| Model | TB4 score | Average cost/task |
| Kimi K3.1 Pro (max) | 65.7% | ~$5.25 |
| Claude Opus 5.5 | ~65.0% | ~$14.30 |
| GPT-6 Astra (max) | 58.2% | ~$10.00 |
| Claude Fable 5.1 (max) | 57.9% | ~$18.90 |
Approximate values read from the supplied cost-performance chart.
Kimi K3.1 Pro costs approximately 63% less per Terminal-Bench task than Opus 5.5, while achieving a similar score.
These figures represent benchmark execution costs, not published API pricing per million tokens.
Kimi K3.1 Pro vs Previous Kimi K3
| Specification | Kimi K3 | Kimi K3.1 Pro |
| Total parameters | 2.8T | 2.8T |
| Architecture | MoE | MoE |
| Active parameters | Not established here | 104B |
| Terminal-Bench 4.0 | No comparable result provided | 65.7 |
| SWE Marathon | No comparable result provided | 51.7 |
| Open weights | Released | Planned Nov. 4 |
Both models have the same reported total parameter count. The supplied materials do not include directly comparable K3 benchmark scores or enough architectural details to quantify generation-over-generation improvements.
Open Weights Coming November 4
Moonshot AI plans to release Kimi K3.1 Pro's open weights on November 4, 2026. The license, hardware requirements and download details have not yet been confirmed.
Conclusion
Kimi K3.1 Pro combines 2.8T total parameters, 104B active parameters and competitive frontier-model performance.
It leads six of 14 reported benchmarks and delivers a Terminal-Bench 4.0 score of 65.7% at approximately $5.25 per task, versus roughly $14.30 for Claude Opus 5.5 in the supplied cost comparison.
The benchmark charts are announcement-supplied results; independent verification remains necessary.