Google introduced EmbeddingGemma 2, a multimodal embedding model for text, code, images, video, and audio.
- up to 740M parameters;
- 8K context window;
- embeddings from 768 to 128 dimensions via Matryoshka Representation Learning;
- modular text, vision, and audio encoders;
- Apache 2.0 license;
- optimized for local and on-device use.
Technical specifications
| Specification | EmbeddingGemma 2 |
| Maximum parameter count | 740M |
| Text/code component | ~270M |
| Vision encoder | ~170M |
| Audio encoder | ~300M |
| Modalities | Text, code, image, video, audio |
| Context window | 8,192 tokens |
| Embedding dimensions | 768, 512, 256, 128 |
| Languages | 100+ |
| License | Apache 2.0 |
The modular architecture means developers can load only the encoders required for a specific application.
Approximate configurations:
- 270M — text and code;
- 440M — text + vision;
- 570M — text + audio;
- 740M — full multimodal setup.
Unified embedding space
EmbeddingGemma 2 maps different input types into the same vector space:
- text → vector
- code → vector
- image → vector
- video → vector
- audio → vector
This enables cross-modal retrieval without converting every input into text first. For example, a text query can retrieve matching images, audio clips, or videos directly from the same vector index.
The main change is not model size, but support for multiple modalities in one embedding space.
EmbeddingGemma 2 vs. EmbeddingGemma
| Feature | EmbeddingGemma | EmbeddingGemma 2 |
| Parameters | ~300M | ~270M–740M |
| Text | Yes | Yes |
| Code | Yes | Yes |
| Images | No | Yes |
| Video | No | Yes |
| Audio | No | Yes |
| Context window | 2K | 8K |
| Max embedding size | 768d | 768d |
| Minimum embedding size | 128d | 128d |
| Multimodal retrieval | No | Yes |
The full 740M size comes mainly from the additional vision and audio encoders. The text/code configuration is about 270M parameters.
Context window
The context window increased from:
2,048 tokens → 8,192 tokens
This allows larger text and code chunks to be embedded without aggressive splitting. For RAG systems, this reduces the risk of separating related definitions, examples, or code blocks across multiple chunks.
Benchmark comparison
| Benchmark | EmbeddingGemma | EmbeddingGemma 2 |
| MTEB Multilingual v2 | 61.15 | 61.36 |
| MTEB Code v1 | 68.76 | 78.68 |
Text retrieval quality is almost unchanged. Code retrieval improves significantly, making the new model more relevant for:
- semantic code search;
- repository indexing;
- coding agents;
- RAG over source code.
Matryoshka Representation Learning
Supported embedding sizes:
768 → 512 → 256 → 128
Smaller embeddings reduce vector database size.
For 1 million vectors stored with 2 bytes per value:
| Dimension | Approx. storage |
| 768 | 1.54 GB |
| 256 | 512 MB |
| 128 | 256 MB |
Reported benchmark results:
| Dimensions | Multilingual MTEB | Code MTEB | Multimodal |
| 768 | 61.36 | 78.68 | 59.01 |
| 512 | 61.17 | 77.24 | 58.38 |
| 256 | 60.41 | 76.18 | 56.24 |
| 128 | 57.89 | 71.41 | 45.65 |
For text and code, 256 dimensions offers a strong size/performance trade-off. For multimodal search, 128 dimensions causes a larger quality drop.
Implementation example
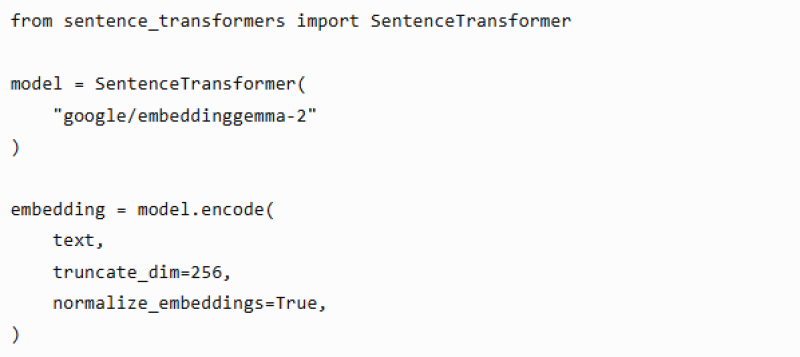
For text-only use:
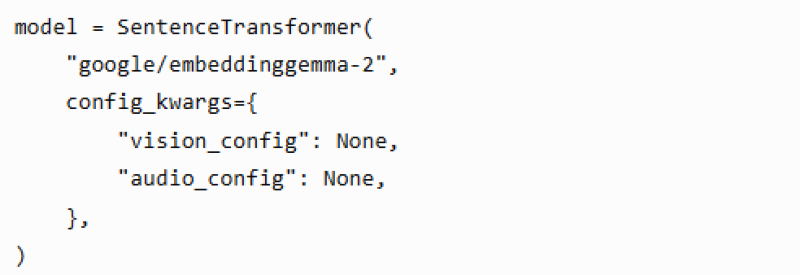
Query and document embeddings must use the same dimensionality.
Precision requirements
Recommended formats:
- bfloat16;
- float32.
Standard float16 is not recommended because activation ranges can exceed FP16 limits and produce unstable or invalid embeddings.
Practical use cases
EmbeddingGemma 2 is most relevant for:
- multimodal RAG;
- semantic code search;
- local document search;
- image and video retrieval;
- audio search;
- privacy-sensitive applications;
- on-device retrieval systems.
A typical pipeline can be reduced to:
text / code / image / audio / video → EmbeddingGemma 2 → vector database
Conclusion
EmbeddingGemma 2 adds three major capabilities over the previous model:
- multimodal embeddings for text, code, images, video, and audio;
- 8K context, up from 2K;
- significantly better code retrieval performance.
For text-only retrieval, the benchmark improvement is small. For code and multimodal retrieval, EmbeddingGemma 2 is a substantial upgrade.